Map your market and benchmark share-of-traffic with Semrush Market Explorer
Semrush Market Explorer sizes a competitive set and shows who owns the traffic. We use it to find whitespace before committing budget, and here is how we get its exports into Power BI.
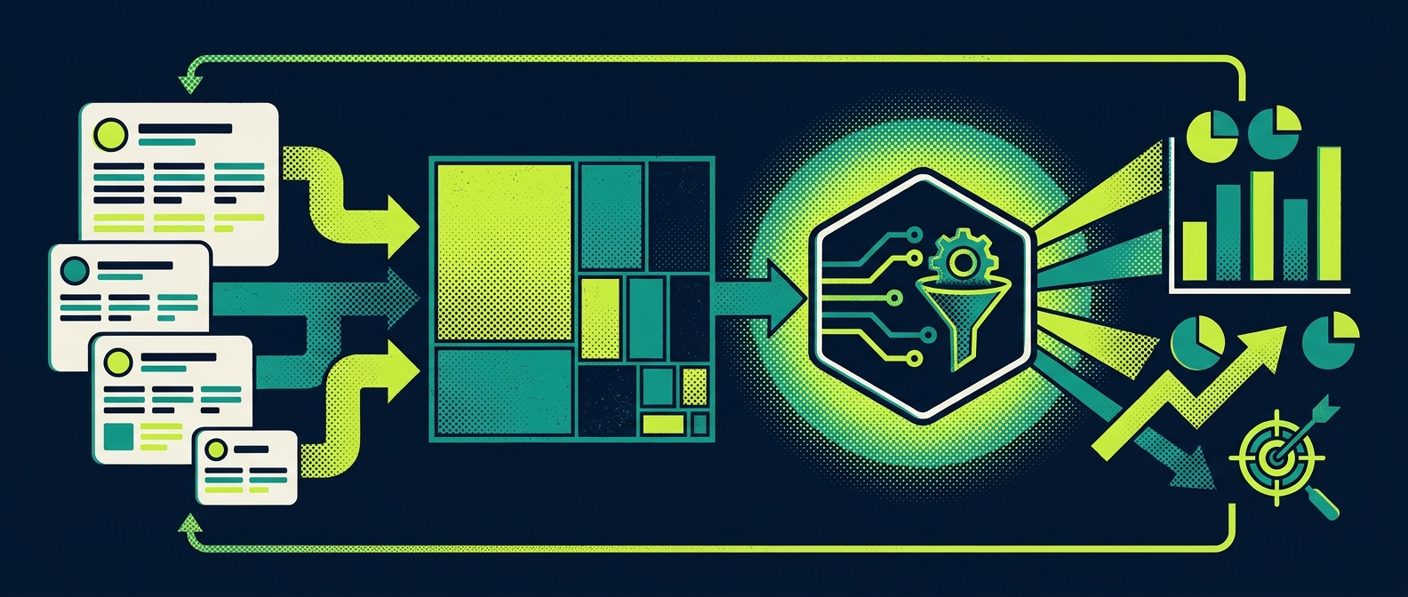
Semrush Market Explorer maps a competitive set, sizes the total traffic in a market, and shows who owns the share of it. We use it to benchmark before a campaign push and to size a segment before entering it. The real problem is getting the export into Power BI cleanly. Here is the Python function we wrote to do it.
01What is Semrush Market Explorer?
Semrush Market Explorer is a competitive-intelligence module inside the Semrush .Trends suite that maps a set of competing domains, sizes the total traffic those domains capture, and breaks down each domain’s share of that traffic. You give it a seed domain or pick a category, and it returns a structured view of who competes for the same audience, how large the demand pool is, and which domains are gaining or losing share.
The data comes from Semrush’s clickstream and panel sources. It does not pull from your own analytics account. That distinction matters. Market Explorer shows the landscape around you, not your own numbers.
Two export formats drive most of our work. The All Domains report lists every domain in the competitive set with its traffic volume, traffic share percentage, and year-over-year growth rate. The Growth report flags which domains are climbing and which are sliding. Both export as CSV. Both land in your downloads folder with column headers that Semrush controls, not you.
02What is Semrush Market Explorer used for?
Semrush Market Explorer is used for three things in our practice: sizing a market before entering it, benchmarking share-of-traffic against a competitive set, and finding whitespace where a challenger can take ground. The use cases below come from client work, not from a demo account.
How large is the market we are entering? For a B2B industrial client, we used Market Explorer to size the segment before committing budget. The questions were concrete: who is already visible in the category, how much demand does it generate, and where is the gap a challenger can take. Market Explorer resolved the set to 68 visible domains generating roughly 43 million visits a year — about 3.6 million a month — with the top three players taking almost two thirds of it. That concentration, not the total, was the finding: the gap for a challenger sat in the fragmented middle, not against the leaders.
Who owns the traffic in this category? For a B2C fashion label preparing a campaign push, we built a competitive set of rival brands alongside the multi-brand retailers that stock them. Market Explorer showed whether a single retailer dominated discovery or whether traffic fragmented across a dozen mid-size players. That answer reshapes the media plan.
Where is the whitespace? The Growth quadrant inside Market Explorer flags domains gaining share against a flat or shrinking market. A domain climbing fast in a category you assumed was settled is a signal worth tracking before the next planning cycle.
The real problem is not running the report. It is getting the export into a shape Power BI can read without breaking every time Semrush renames a column.
03How do you get Semrush Market Explorer data into Power BI?
Getting Semrush Market Explorer data into Power BI requires a transform step between export and import. The raw CSV exports change shape when Semrush updates field names, and Power BI expects consistent columns, predictable data types, and no gaps on every refresh.
We wrote a Python function to bridge that gap. It does four things in sequence. It verifies that the input and mapping files exist before touching anything, so a missing file fails loudly at the top of the log instead of crashing mid-transform. It loads a mapping CSV that translates Semrush’s current column names to a stable set we own. It reindexes the data so every expected column is present, filling gaps with empty strings for text and zeros for numbers. Then it writes a clean CSV Power BI can consume.
Here is the function, verbatim from our pipeline:
import pandas as pd
import os

def verify_file_path(path):
    """Check if a file exists at the given path and print a message."""
    if os.path.exists(path):
        print(f"File found: {path}")
        return True
    else:
        print(f"File not found: {path}")
        return False

def transform_and_prepare_for_power_bi(input_file_path, mapping_file_path, output_file_path):
    # Verify file paths
    if not verify_file_path(input_file_path) or not verify_file_path(mapping_file_path):
        return  # Exit the function if any file is missing

    # Load the mapping table with the correct delimiter
    mapping_data = pd.read_csv(mapping_file_path, delimiter=';')
    mapping_dict = mapping_data.dropna().set_index('Mapping.New')['Mapping.Old'].to_dict()

    # Load the data
    data = pd.read_csv(input_file_path)

    # Rename columns according to the mapping table, reindex to ensure all 'Mapping.Old' columns are present
    data_transformed = data.rename(columns=mapping_dict).reindex(columns=mapping_data['Mapping.Old'].tolist(), fill_value="")

    # Filling missing values - empty strings for text, 0 for numbers
    text_columns = data_transformed.select_dtypes(include=['object']).columns
    numeric_columns = data_transformed.select_dtypes(include=['number']).columns
    data_transformed[text_columns] = data_transformed[text_columns].fillna("")
    data_transformed[numeric_columns] = data_transformed[numeric_columns].fillna(0)

    # Save the transformed data
    data_transformed.to_csv(output_file_path, index=False, encoding='utf-8')
    print(f"Data transformed and saved successfully to {output_file_path}")

# Define file paths within the main block of the script to ensure they are recognized
input_file_path = 'Your Input File Path!\\2024-03-Worldwide.csv'
mapping_file_path = 'Your Mapping File Path!\\mapping-semrush.csv'
output_file_path = 'Your Output Path!\\Transformed_Data_for_PowerBI.csv'

# Run the transformation function
transform_and_prepare_for_power_bi(input_file_path, mapping_file_path, output_file_path)
Three design decisions in this function are worth naming.
Path verification runs first. The verify_file_path() function checks both the input CSV and the mapping CSV before any transformation starts. If either file is missing, the function prints the missing path and exits. No partial output. No silent failure.
The mapping CSV is a file you own. mapping-semrush.csv has two columns: Mapping.New holds whatever Semrush currently calls a field, and Mapping.Old holds the name Power BI expects. When Semrush renames a column, you change one row in this CSV. You do not touch your Python script, your Power BI model, or your DAX measures.
Reindex enforces the output shape. The reindex(columns=..., fill_value="") call guarantees the output always has exactly the columns Power BI expects, in the same order, regardless of what the source export contains. A column Semrush removed gets filled with zeros or empty strings instead of breaking the import.
04How do you keep the pipeline stable when Semrush changes export fields?
You keep the pipeline stable with a mapping CSV that translates Semrush’s current field names to a fixed set you control. The pattern generalises beyond any single Semrush update.
In March 2024, Semrush restructured the dimensions in the Trends Market Explorer All Domains report. Column names changed. Some fields were consolidated, others were split. Dashboards that read the old column names broke on the next refresh. Instead of patching Power BI queries or rebuilding the import script, we updated the mapping CSV to translate the new field names back to the ones our model already expected. Historical data in Power BI kept its column shape. New exports landed in the same columns under the same names.
That is the pattern. Any time Semrush changes a field name, you update one row in a CSV you control. Your Power BI model does not move. Your DAX measures do not break. Your year-over-year comparisons stay intact because the column names never change downstream of the mapping.
- 01Two columns:
Mapping.New(Semrush's current field name) andMapping.Old(your stable name) - 02Delimiter is semicolon, not comma, to avoid conflicts with values that contain commas
- 03Version it. Every time Semrush changes a field, add a dated row and keep the old one for reference
- 04Store it next to your transform script, not inside the Power BI model
05What does the full workflow look like?
From competitive set to Power BI dashboard, the pipeline runs in four steps:
Once the pipeline is set up, a monthly refresh takes minutes. Export from Semrush, run the script, refresh Power BI. The mapping CSV absorbs any field-name changes Semrush ships in between, so the downstream model never sees them.